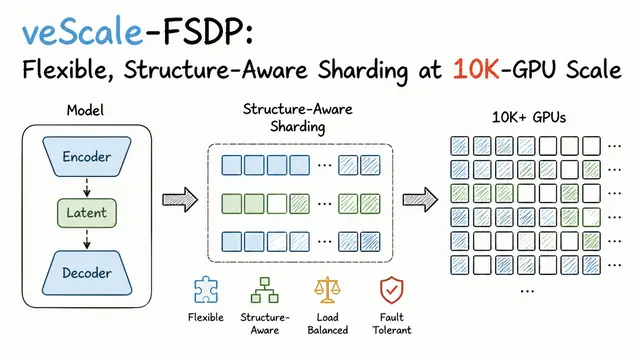
veScale-FSDP: Flexible, Structure-Aware Sharding at 10K-GPU Scale
Suppose you want to train a model with a matrix optimizer such as Muon. The optimizer does not think of a weight matrix as a bag of ...
Distributed Machine Learning SystemsFSDPRaggedShard