Search the public knowledge base.
4 results
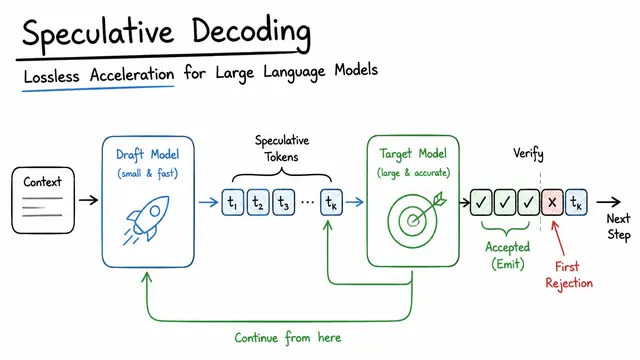
Speculative Decoding in LLM's
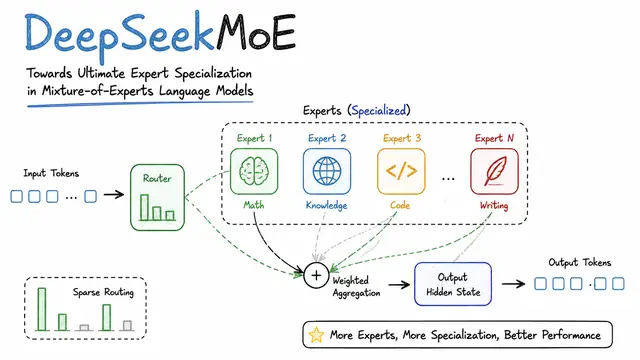
MoE architecture for efficient LLM scaling via specialized experts
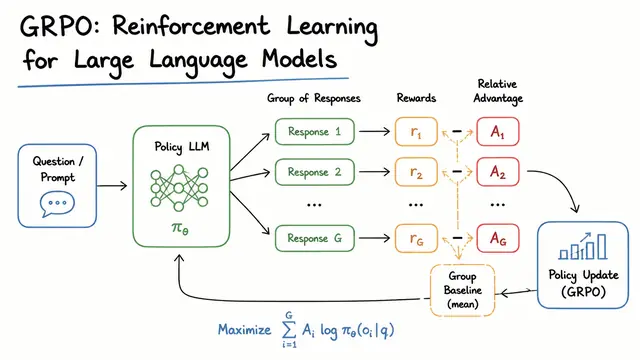
GRPO and RL for LLM's
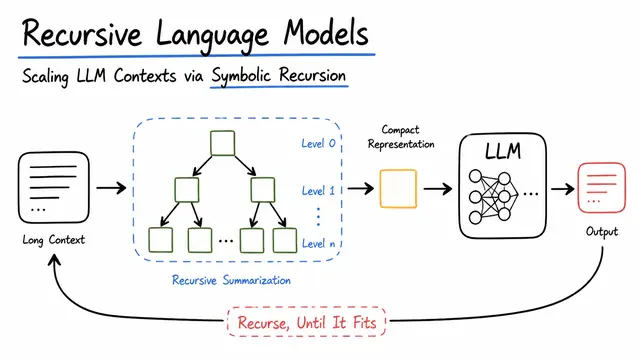
Language models that recursively refine or compose intermediate reasoning/representations.
