FeynmanWiki
ExploreLibraryRoadmapsCreateMy blogsPricing
← All roadmaps
Language Models

LLM Systems & Inference

Understand how language models store capacity, manage context, and serve tokens efficiently at scale.
Advanced6 visual deep dives
1

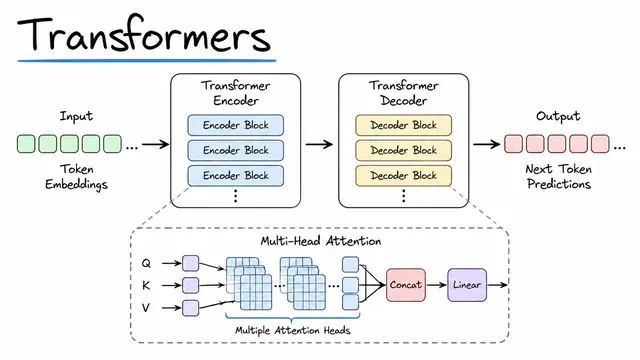
Transformers: Attention, Architecture, Training, and Scaling

Transformers

84 min read
›
2

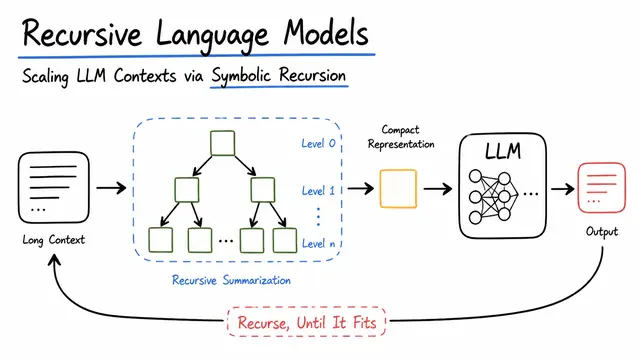
Recursive Language Models: Scaling LLM Contexts via Symbolic Recursion

Language models that recursively refine or compose intermediate reasoning/representations.

45 min read
›
3

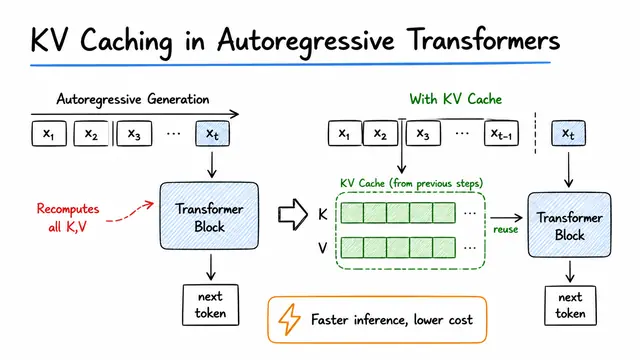
KV Caching in Autoregressive Transformers

KV Caching

45 min read
›
4

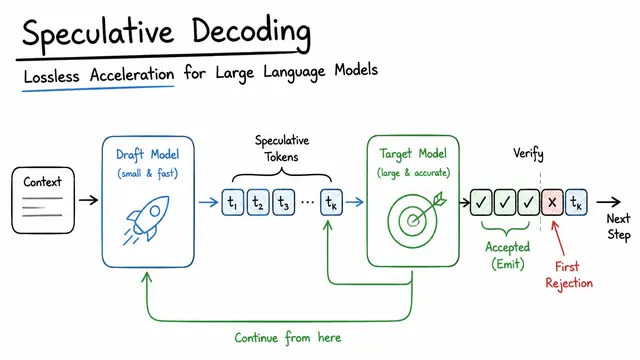
Speculative Decoding: Lossless Acceleration for Large Language Models

Speculative Decoding in LLM's

45 min read
›
5

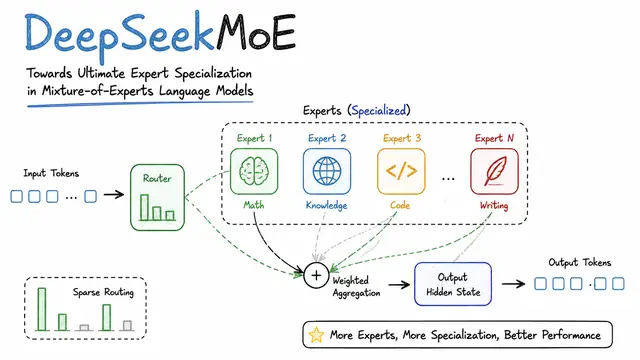
DeepSeekMoE: Towards Ultimate Expert Specialization in Mixture-of-Experts Language Models

MoE architecture for efficient LLM scaling via specialized experts

45 min read
›
6

Harness Engineering: Building Reliable Evaluation and Data Pipelines for ML Systems

Harness engineering

45 min read
›